AI Acceptance Testing for Saudi Enterprises: A Governance-First Checklist What is AI acceptance testing?
AI acceptance testing determines whether an AI system performs its agreed business task reliably, remains within its authorized boundaries, protects organizational and personal data, escalates appropriate cases to humans, and delivers measurable value.
Unlike traditional User Acceptance Testing (UAT), testing an AI agent must account for variable outputs, unsupported answers, incorrect source retrieval, security attacks, bilingual performance, tool permissions, and unexpected real-world scenarios.
For Saudi enterprises, acceptance testing should support—but does not replace—PDPL assessments, cybersecurity reviews, AI governance, and internal risk management. Its purpose is to produce evidence that decision-makers can use to approve, restrict, improve, or reject an AI deployment.
Why does AI acceptance testing matter for Saudi enterprises?
Saudi organizations are adopting AI to improve procurement, customer service, operations, marketing, recruitment, and knowledge management. An AI pilot may perform well during a controlled demonstration but behave differently when connected to real data, users, and business systems.
An AI agent can fail in several ways. It may retrieve the wrong document, invent missing information, misunderstand Arabic terminology, expose information to an unauthorized user, or attempt an action beyond its approved authority.
These failures are different from conventional software defects. Traditional software normally follows predefined rules, while AI output can vary according to the prompt, context, model, source data, and available tools.
This is why AI acceptance testing must go beyond asking whether the system works. It must answer:
Does the system complete the intended task? Are its answers supported by approved sources? Does it follow business rules consistently? Can it recognize when information is insufficient? Does it remain within its permitted access? Does it escalate high-risk cases appropriately? Can the organization investigate what happened? Does the system create measurable operational value?
For CIOs, COOs, compliance teams, procurement leaders, and business owners, these answers create the basis for a defensible go/no-go decision.
Is AI acceptance testing the same as UAT?
AI acceptance testing includes UAT, but it is broader.
User Acceptance Testing evaluates whether the system meets business and user requirements. An enterprise AI assessment should also include:
AI output evaluations, commonly called evals. Retrieval and source-grounding tests. Privacy and data-governance reviews. Security and adversarial testing. Integration and permission testing. Human-oversight validation. Operational readiness testing. Post-deployment monitoring plans.
Passing UAT does not prove that an AI system is compliant with the Saudi Personal Data Protection Law. PDPL readiness also depends on matters such as the processing purpose, legal basis, transparency, data minimization, retention, security, processor arrangements, data-subject rights, and cross-border transfers.
Acceptance testing should therefore document which controls were tested without making a general claim that the entire system or organization is legally compliant.
What Does a Seven-Step AI Acceptance Testing Checklist Include?
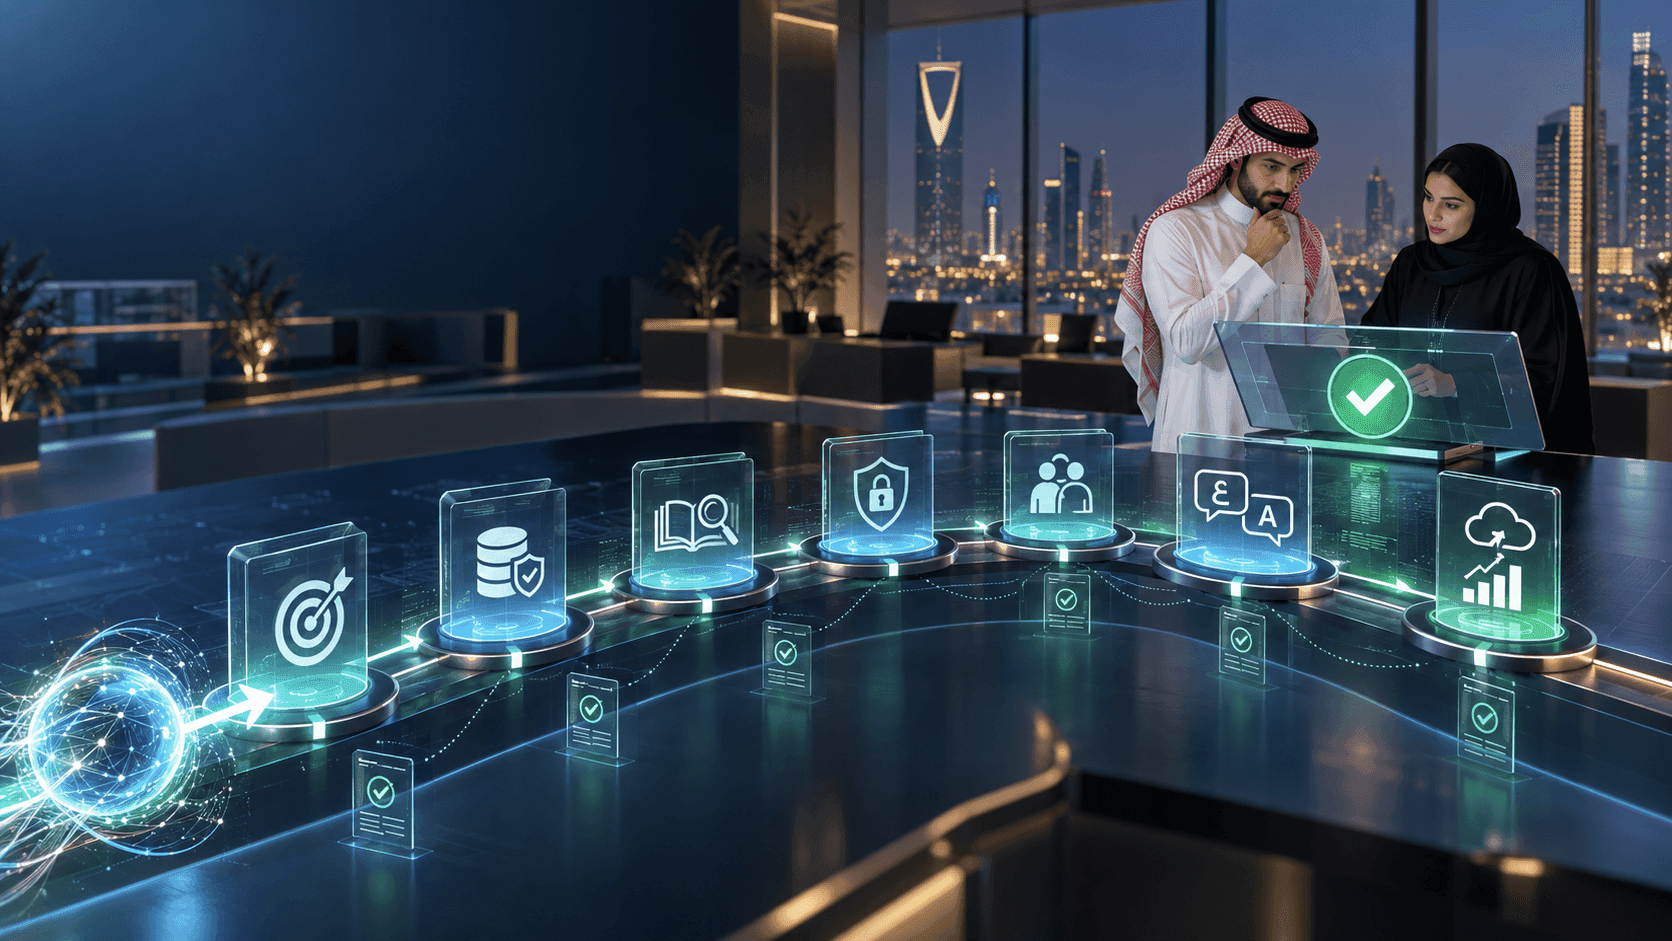
A governance-first checklist should cover seven acceptance gates:
Business scope and risk. Representative test data. Output quality and source grounding. Permissions, security, and failure boundaries. Human oversight. Bilingual and operational performance. Deployment approval and continuous monitoring.
Each gate should have documented evidence and predefined pass, conditional-pass, or fail criteria.
Step 1: Define the Use Case, Risk Level, and Acceptance Criteria
Before testing the AI, define exactly what it is expected to do.
Avoid broad goals such as “improve procurement” or “answer customer questions.” Instead, specify the workflow, users, source systems, permitted actions, and desired outcome.
For example, an RFQ-to-quote pilot might be responsible for:
Reading an incoming RFQ. Extracting required product and customer information. Identifying missing fields. Retrieving approved product and pricing data. Preparing a draft quotation. Routing exceptions for human review.
The acceptance criteria should combine business value, output quality, operational performance, and risk controls.
Relevant metrics may include:
Quote turnaround time. Required-field extraction accuracy. Business-rule application accuracy. Unsupported-claim rate. Human correction rate. Escalation accuracy. Percentage of cases completed without rework. Cost per completed workflow.
Do not adopt an arbitrary accuracy target. The acceptable threshold should reflect the task and the consequences of an error. A low-risk internal summary and a customer-facing commercial quotation should not have identical standards.
The pilot scope should also identify prohibited actions and automatic deployment blockers. These may include unauthorized data access, sending an unapproved quotation, exposing confidential pricing, or failing to escalate a high-risk exception.
Step 2: Build a Representative and Governed Test Dataset
A system that succeeds only on ideal examples is not ready for production.
The test set should represent the requests, documents, languages, and exceptions the AI will encounter in the real workflow. It should include:
Common requests. Incomplete submissions. Ambiguous instructions. Conflicting information. Outdated documents. Unsupported requests. Unusual file formats. High-volume periods. High-value or high-risk cases. Attempts to access unauthorized information.
Keep part of the evaluation dataset separate from the examples used to configure the agent. Testing the system only on familiar examples can create a misleading picture of performance.
Personal and confidential information must also be governed during testing. Use synthetic, anonymized, or masked data when it can meet the testing objective. If identifiable data is necessary, document why it is required, who can access it, where it will be processed, and when it will be deleted.
Data minimization remains important: include only the information required for the defined test.
If data will be stored, accessed, or processed outside Saudi Arabia, the organization should assess the applicable PDPL transfer requirements and safeguards. Data residency should not be reduced to a checkbox or a general promise from the vendor.
Step 3: Test Accuracy, Grounding, and Business Rules
AI quality cannot be represented by one general accuracy score. Different components of the workflow should be measured separately.
Test whether each output is:
Supported by approved information. Relevant to the request. Complete enough for its purpose. Consistent with applicable business rules. Clear to the intended user. Properly cited when citations are required. Free from invented facts or unsupported claims.
For a retrieval-augmented generation system such as OpsRAG, evaluate retrieval and answer generation separately.
Ask:
Did the system find the correct document? Did it retrieve the relevant section? Was the source current and authorized? Did the final answer accurately reflect that source? Did the system acknowledge missing or conflicting information?
A fluent answer is still a failure if it uses an outdated policy or invents information not found in the approved knowledge base.
Create separate failure categories, such as incorrect retrieval, missing information, unsupported generation, business-rule violation, and formatting error. This makes the results easier to diagnose and improve.
Step 4: Test Read-Only-First Access, Security, and Failure Boundaries
An AI agent should begin with the minimum access required for the pilot.
Read-only-first means limiting the agent initially to retrieving approved information without allowing it to modify records, send communications, approve transactions, or delete data unless these actions have been explicitly authorized and tested.
Acceptance testing should confirm:
Which systems the agent can access. Which records it can retrieve. Which tools or APIs it can invoke. Which actions require human approval. Whether access follows least-privilege principles. Whether credentials and secrets are protected. Whether data interactions are logged.
Security testing should include attempts to:
Retrieve another user’s or department’s data. Override system instructions. Extract confidential information. Trigger unauthorized actions. Manipulate the agent through content embedded in documents. Submit malicious or unexpected attachments. Bypass approval steps. Cause duplicate or repeated actions.
The agent must also fail safely. If a source system is unavailable, a required field is missing, or available evidence conflicts, the system should stop, explain the limitation, or escalate the case. It should not invent an answer simply to complete the workflow.
For a WhatsApp customer-experience use case, testing should cover not only the agent’s ability to read customer information but also whether it can send messages, change records, expose information across conversations, or act without the required approval.
Step 5: Validate Human Oversight and Escalation
Human-in-the-loop is effective only when the approval and escalation logic has been clearly designed.
Requiring human approval for every action can eliminate the efficiency benefit. Allowing unrestricted autonomy can expose the organization to unacceptable risk. The level of oversight should match the impact of the decision.
Test whether the agent:
Recognizes defined approval thresholds. Escalates low-confidence or high-impact cases. Explains why review is required. Provides supporting evidence to the reviewer. Prevents action before approval. Routes the case to the correct role. Records the reviewer’s decision. Handles rejection and correction properly.
For SmartQuote, a request that conflicts with an approved pricing rule, includes missing commercial terms, or exceeds a discount threshold may require human review. The exact conditions should be defined during pilot scoping rather than assumed for every organization.
Human reviewers should also be able to identify what the AI proposed, which information it used, what was changed, and who approved the final output.
Step 6: Test Arabic, English, Integrations, and Operational Performance
Saudi enterprises commonly operate across Arabic and English documents, systems, and conversations. Language testing should therefore evaluate business accuracy—not just general fluency.
The test set should cover:
Modern Standard Arabic. Relevant Saudi business terminology. English and Arabic documents in the same knowledge base. Mixed-language requests where users commonly submit them. Spelling and transliteration variations. Arabic names and addresses. Dates, currencies, numbers, and units. Right-to-left display. Arabic tables and scanned documents. Source citations in the appropriate language.
Arabizi or conversational dialects should be tested when they reflect the actual use case, such as customer communication over WhatsApp. They may not be necessary for every internal enterprise workflow.
The agent should be assessed for equivalent meaning across languages. A policy answer should not change materially simply because the user switches from English to Arabic.
Operational testing should also cover:
Response time. Peak-volume performance. Integration reliability. Duplicate actions. Recovery after interruptions. Cost per request or completed task. Manual fallback procedures. User experience and accessibility.
Collect structured feedback from the employees who will use the system. However, keep user satisfaction separate from objective measurements of accuracy, risk, and operational performance.
Step 7: Make a Documented Go/No-Go Decision
The result of acceptance testing should be a formal deployment decision—not a general impression that the demonstration went well.
The acceptance record should include:
The approved use case and scope. Test cases and dataset versions. Metrics and acceptance thresholds. Passed and failed scenarios. Known limitations. Unresolved issues and residual risks. Required controls and mitigations. Approved data sources and integrations. Model, prompt, and knowledge-base versions. Permissions granted to the agent. Human-review and escalation rules. Rollback and manual fallback procedures. Owners responsible for approval and monitoring.
The business owner, IT team, cybersecurity, privacy or compliance stakeholders, operational users, and AI provider should participate according to the organization’s governance structure.
A failed test does not always mean that the entire pilot must be abandoned. It may produce one of three decisions:
Go: The system meets the agreed requirements. Conditional go: Deployment can proceed with defined restrictions and remediation. No-go: A critical requirement or risk threshold has not been satisfied.
Acceptance records provide evidence of what was evaluated and approved. They do not, on their own, prove full PDPL compliance.
What Happens After the AI Agent Goes Live?
AI acceptance testing does not end at deployment.
Performance may change when source documents are updated, users submit unfamiliar requests, integrations change, prompts are revised, or a different model version is introduced.
Production monitoring should track:
Unsupported or incorrect outputs. Human overrides and corrections. Escalation frequency. Unauthorized-access attempts. Security incidents. User complaints. Response time and availability. Cost per workflow. Changes in Arabic and English performance. Differences between pilot and production results.
Material changes to the model, system prompt, business rules, knowledge base, permissions, or integrations should trigger regression testing. High-impact changes may also require renewed approval before release.
The organization should maintain an incident process that allows the AI workflow to be paused, restricted, or rolled back when unexpected behavior is identified.
How Does This Checklist Apply to a LeenAI Pilot?
LeenAI’s enterprise AI approach can begin with a fixed-scope pilot tied to a measurable workflow. Instead of attempting a broad transformation immediately, the organization can define the process, connect only the required sources, establish human approval points, and evaluate the system against agreed acceptance criteria.
Depending on the use case, the pilot may evaluate:
SmartQuote for RFQ-to-quote workflows. WhatsApp CX for customer-service resolution. OpsRAG for grounded access to operational knowledge. Other governed AI workflows for marketing, recruitment, or operations.
The specific metrics, access permissions, processing locations, integrations, and approval rules should be documented for each customer and use case. They should not be assumed to be identical across deployments.
This approach gives stakeholders practical evidence about value, limitations, and risk before the organization expands the agent’s permissions or deploys it across additional departments.
Frequently Asked Questions What is AI acceptance testing?
AI acceptance testing evaluates whether an AI system meets agreed business, quality, security, privacy, and operational requirements before production deployment. It also tests how the system behaves when information is incomplete, conflicting, or outside its authority.
How is AI acceptance testing different from traditional UAT?
Traditional UAT usually tests predefined functions and workflows. AI testing must also evaluate variable outputs, source grounding, unsupported answers, security attacks, language performance, tool permissions, human escalation, and failure behavior.
Does passing AI UAT prove PDPL compliance?
No. Testing can demonstrate that specific privacy and security controls were evaluated. PDPL compliance also depends on the processing purpose, legal basis, transparency, retention, data-subject rights, security, processor arrangements, and applicable cross-border transfer requirements.
What data should be used for AI testing?
Use representative data covering routine, difficult, and high-risk scenarios. Synthetic, anonymized, or masked data should be used when it can meet the testing objective. Any use of identifiable or confidential data should have a documented purpose and appropriate controls.
How should an enterprise measure AI accuracy?
The measurement should reflect the task. An RFQ agent may be evaluated on field extraction, business-rule application, unsupported claims, required corrections, escalation quality, and turnaround time. A RAG system should be tested separately for retrieval and answer quality.
Why is human-in-the-loop testing important?
It confirms that the system pauses or escalates when its authority, confidence, or evidence is insufficient. It also ensures that the human reviewer receives enough information to approve, reject, or correct the proposed action.
How should Arabic AI performance be tested?
Test relevant Saudi terminology, Arabic and English documents, spelling variations, names, dates, currencies, right-to-left display, mixed-language requests where appropriate, and the accuracy of retrieval and citations.
What is read-only-first access?
Read-only-first limits an AI agent initially to retrieving approved information. Write, send, approve, or delete permissions are introduced only when the business need, safeguards, approval rules, and test results support them.
When should an AI agent be retested?
Retesting should occur after material changes to the model, prompts, knowledge sources, integrations, permissions, or business rules. Regression testing should also be scheduled as part of ongoing production monitoring.
Prove Value Before Scaling
A successful AI pilot is not defined by an impressive demonstration. It is defined by evidence that the system performs the intended task, remains within approved boundaries, supports human control, and creates measurable business value.
For Saudi enterprises, governance-first acceptance testing provides a practical path from experimentation to responsible production deployment.
Talk to LeenAI about scoping a measurable enterprise AI pilot, or explore the SmartQuote pilot for governed RFQ-to-quote automation.