Why does Vision 2030 make governed AI a board-level question?
Vision 2030 set a direction for the Saudi economy that depends on operational productivity, diversified revenue, and a digital public and private sector. For an enterprise, that direction shows up as pressure: do more with the team you have, respond faster to customers, and keep every riyal of spend defensible. AI is now part of that conversation in almost every boardroom, but the useful question is not whether to adopt it. It is how to adopt it without creating a compliance, quality, or reputational problem you cannot unwind.
The enterprises that move well treat AI as an operational capability, not a technology purchase. They start from a workflow that already hurts — quotations that take days, a WhatsApp inbox that never clears, documents nobody can find — and they ask what a governed agent could take off the team's plate. That framing keeps the discussion on measurable outcomes rather than model names, and it makes the first project small enough to actually finish.
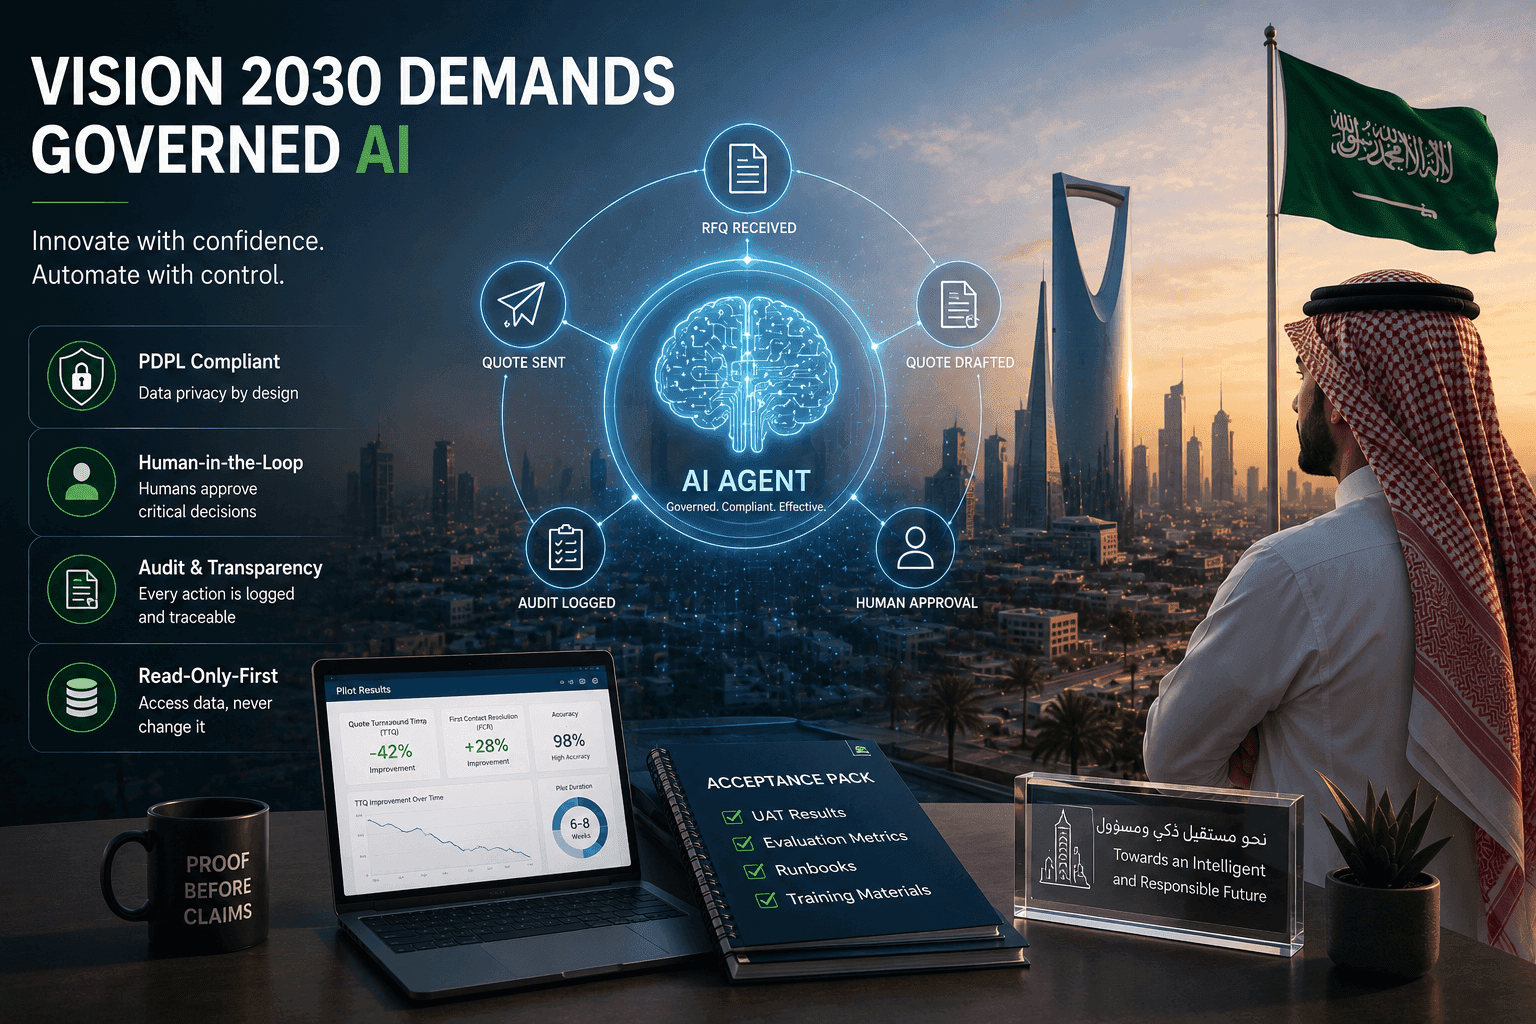
Governance is what separates a pilot that scales from one that stalls. If the agent reads data it should not touch, or produces an answer no one can trace, the project dies in review regardless of how impressive the demo looked. Read-only-first access, human-in-the-loop approval, role-based permissions, and audit logs are not bureaucracy; they are the reason a Saudi enterprise can say yes to production.
What does a governed AI agent actually look like in daily operations?
A governed agent is a system that acts inside boundaries you define and leaves a record of every action. In practice that means four things. First, it starts read-only: it can retrieve and draft, but it cannot send, post, pay, or change a record until you decide otherwise. Second, a named human approves anything that leaves the company. Third, every step is logged with who asked, what the agent used, and what it produced. Fourth, the data it can see is minimized to what the task requires.
Consider a quotation workflow. An agent reads an incoming RFQ, matches line items against your catalog, applies your pricing rules, and produces a quote draft. A human reviews and sends. The agent never invents a price, never emails a customer on its own, and every draft is traceable to the catalog and rule that produced it. That is the difference between automation you can defend and automation you have to apologize for.
The same pattern applies across functions. In customer service, an agent answers common questions from an approved knowledge base, marks itself clearly as AI, and escalates the rest to a human with full context. In operations, employees ask questions in plain language and get answers with citations from approved documents, never invented ones. In HR, CVs in Arabic and English are matched against a job description, and a recruiter still makes the call. The common thread is that the agent does the reading, matching, and drafting, while your people keep the decision.
How do you choose the first workflow to transform?
Choose by friction and measurability, not by ambition. The right first workflow has three properties: it happens often, it consumes skilled people's time on repetitive reading or drafting, and its output can be measured against a baseline you already have. If you cannot describe what "better" means in a number today, you cannot prove the pilot worked tomorrow.
A useful test is to list the workflows where your team is a bottleneck between an incoming request and a response. RFQs waiting for quotes, customer messages waiting for answers, contracts waiting for review, candidates waiting for screening. These queues are where governed agents pay back fastest, because the work is structured, the volume is real, and the human approval step is natural rather than forced.
Resist the temptation to start with the most complex or most visible process. A large, cross-department transformation as a first project usually produces a long discovery phase, unclear ownership, and no acceptance criteria anyone agrees on. One workflow, one owner, one baseline, one decision gate. That is how you build the internal evidence and confidence that make the second and third projects easy to approve.
What should a 6-to-8-week governed pilot deliver?
A serious pilot has a fixed scope, locked deliverables, and defined acceptance criteria agreed before work starts. At LeenAI, a Full Pilot runs SAR 60,000 to 80,000 over 6 to 8 weeks, and a Mini-Pilot runs SAR 20,000 to 30,000 over 2 to 3 weeks when you want to test one narrow workflow first. The point of the range is that you know the cost before you commit, not after.
Inside those weeks you should expect a baseline measurement of the current process, a working system on your real data in a controlled environment, user acceptance testing with the people who will actually use it, and an Acceptance Pack that documents what was built, what it does, how it was tested, and what the results were. If the pilot misses the agreed criteria, you have a documented no-go decision and you stop. That gate is a feature, not a failure.
You can see how we scope pilots and what a fixed-scope engagement includes. The important governance principle is that the customer owns the system and all artifacts. You are not renting access to a black box; you are building an asset your team can run, audit, and extend. If you want to start with a single workflow and a 24-hour response on scope, timeline, and SAR cost, talk to us.
How does PDPL shape an AI pilot from day one?
PDPL compliance is easier when it is designed in than when it is retrofitted. Before any code is written, you should be able to answer: what personal data does the agent see, where does it live, who can access it, how long is it retained, and what is the legal basis for processing it? If those answers are vague, the pilot is not ready to touch production data.
Data minimization is the practical lever. An agent that answers HR policy questions does not need access to salary records. An agent that drafts quotes does not need customer personal data beyond what the RFQ contains. Scoping access tightly reduces both compliance risk and the blast radius of any error. Pair that with role-based access control, documented retention rules, and audit logs, and you have the controls a Saudi enterprise needs to satisfy its own risk and legal functions.
Human-in-the-loop is the second lever. Keeping a person as the approver for outbound actions means the agent's mistakes become drafts to correct, not incidents to manage. For customer-facing channels, marking the agent clearly as AI is both an ethical choice and a trust-building one; customers in the Kingdom respond well to transparency when the service is genuinely faster. These choices are not obstacles to Vision 2030 ambitions — they are what make those ambitions sustainable.
What separates enterprises that scale AI from those that stall?
The ones that scale treat each pilot as a decision, not a demonstration. They define the baseline, run the pilot, read the Acceptance Pack, and either expand or stop with evidence. Over several quarters this produces a portfolio of governed agents across quotations, customer service, knowledge search, marketing, and recruitment — each one owned, measured, and reversible.
The ones that stall usually skipped a step. They bought a platform before choosing a workflow. They let scope expand mid-pilot. They never agreed on what success meant. Or they let an agent act on data before governance was in place, and the first incident froze the whole program. None of these are technology failures; they are sequencing failures.
A pragmatic sequence for a Saudi enterprise looks like this: run a diagnostic to pick the workflow and assess data readiness, run one governed pilot with fixed scope and acceptance criteria, then use the evidence to decide the next two workflows. LeenAI's AI Consulting exists precisely to help you pick the right workflow and avoid overbuilding before you commit. Vision 2030 rewards enterprises that move with evidence and control — proof before claims, one governed workflow at a time.